layout: true --- class: inverse, center, middle background-image: url(../figs/titlepage16-9.png) background-size: cover <br> <br> # Bayesian Statistics and Computing ## Lecture 0: Course Introduction <img src="../figs/slides.png" width="150px"/> #### *Yanfei Kang | BSC | Beihang University* --- # General information - **Credits: ** 2 credits - **Lecturer: ** Yanfei Kang. For now, you can know me better via my personal webpage: http://yanfei.site. - **Tutor:** Shun Hu - **Language: ** Taught in Chinese. Materials are in English. - **Computer language: R** - **Reception hours: ** Questions concerned with this course can be asked via email: yanfeikang@buaa.edu.cn. - **Lecture notes: ** available on on *https://yanfei.site/teaching/bsc*. --- # References 1. [Computational Statistics (Chinese version)](https://yanfei.site/docs/statscompbook/index.html). Yanfei Kang and Feng Li. In progress. 2026. 2. [Advanced statistical computing](https://bookdown.org/rdpeng/advstatcomp/). Roger Peng. In progress. 2022. 3. [Introduction to scientific programming and simulation using R](https://yanfei.site/docs/sc/spuRs.pdf). Owen Jones, Robert Maillardet, Andrew Robinson. 2nd Edition. CRC press. 2014. ISBN: 9781466569997. 4. [Computational Statistics](https://yanfei.site/docs/sc/cs_Gentle.pdf). James E. Gentle. Springer. 2009. ISBN: 9780387981437. --- # Motivation - We’ve derived many statistical formulas in class — but how are these formulas actually computed by a computer? - What happens when the matrix is too large, the integral cannot be solved analytically, or the model has no closed-form solution? Can statistics still proceed? - Have you ever encountered a situation where “the formula looks correct, but the program doesn’t run”? Why does that happen? --- # Unit objectives 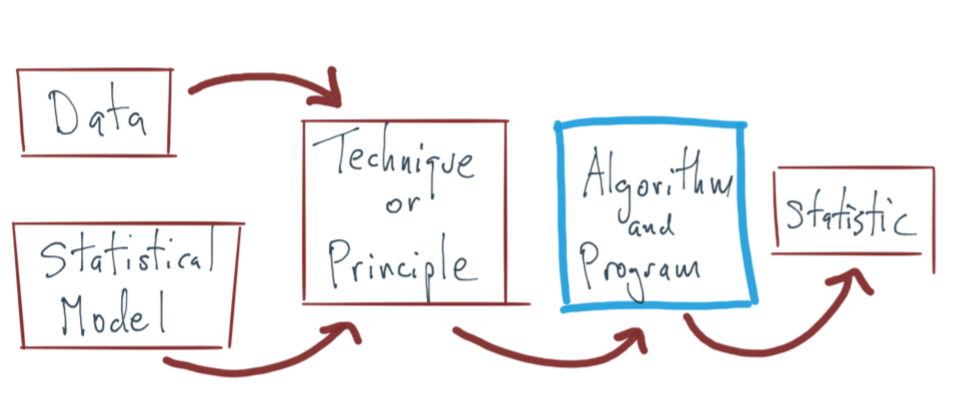 --- # Example: linear models Consider the simple linear model: `$$y = \beta_0 + \beta_1 x + \epsilon.$$` | Component | Implementation | | :-------- | :------------- | | Model | Linear regression | | Principle/Technique | Likelihood principle | | Algorithm | Maximization (analytical) | | Statistic | `\(\beta_0\)`, `\(\beta_1\)` | -- 👉 **Statistical Computing makes Statistical inference possible!** --- # Two statements #### *Computer numbers are not the same as real numbers, and the arithmetic operations on computer numbers are not exactly the same as those of ordinary arithmetic.* #### *The form of a mathematical expression and the way the expression should be evaluated in actual practice may be quite different.* --- # Key issues on the computer 1. Overflow - `NA`s or `Inf`s for very big numbers. 2. Underflow - Similar. 3. Near linear dependence in matrix computation. *Finite precision nature of computer arithmetic*: computers can represent a finite number of numbers. ```r .Machine$double.xmin #> [1] 2.225074e-308 ``` *Note that on most platforms smaller positive values than .Machine$double.xmin can occur. On a typical R platform the smallest positive double is about 5e-324.* --- # Textbooks vs. computers - Disconnection between textbook and what *should* be implemented on the computer. - Textbooks: convenient mathematical formulas. - Computers: directly translating these formulas into computer code is usually not advisable. 👉 Theory tells you *what* to compute; computation tells you *how* to actually compute it. --- # Eg1: Using Logarithms Consider the univariate Normal distribution - We compute this value using `dnorm()` in R. ```r dnorm(1) #> [1] 0.2419707 ``` - How about `dnorm(40)`? - Usually you can get away with computing the log of this value (and with `dnorm()` you can set the option `log = TRUE`). - Computing densities with logarithms is much more numerically stable. - `\(\frac{f(x)}{g(x)}\)` `\(\Rightarrow\)` `\(\exp(\log f(x) - \log(g(x)))\)`. --- # Eg2: Matrix inversion: `\(A^{-1}\)` - When `\(n = 3\)`, we can compute `\(A^{-1}\)` by hand. - When `\(n = 1000\)`, matrix inversion involves roughly `\(10^9\)` operations. 👉 At this point, it is no longer a purely mathematical problem—it becomes one of **algorithms and numerical stability**. - The choice among LU decomposition, QR decomposition, SVD, or iterative methods (such as conjugate gradient) determines whether the result is **computable and reliable**. --- # Matrix inversion: `\(A^{-1}\)` ``` r # Large matrix: needs efficient numerical algorithms set.seed(123) A_large <- matrix(rnorm(1000^2), nrow = 1000) # Solve a linear system A * x = b efficiently b <- rnorm(1000) library(microbenchmark) microbenchmark(solve(A_large) %*% b, # direct inversion solve(A_large, b) # uses LU decomposition ) #> Unit: milliseconds #> expr min lq mean median uq max neval #> solve(A_large) %*% b 742.3504 847.5188 904.9561 891.7551 942.0188 1186.9988 100 #> solve(A_large, b) 191.8835 202.5194 211.7110 209.6339 215.6981 276.1967 100 ``` --- # Eg3: Solution to linear regression Linear regression model in matrix form: `$$y = X\beta + \varepsilon.$$` - The solution is written as `$$\hat{\beta} = (X^\prime X)^{-1}X^\prime y.$$` - In R, this could be translated literally as ```r betahat <- solve(t(X) %*% X) %*% t(X) %*% y ``` - The formula presented above is *only* computed in textbooks. - The direct inverse of `\(X^\prime X\)` is very expensive computationally. --- # Simpler approaches - Take the normal equations, `$$X^\prime X\beta = X^\prime y$$` and solve them directly. - In R, we could write ```r solve(crossprod(X), crossprod(X, y)) ``` - Rather than compute the inverse of `\(X^\prime X\)`, we directly compute `\(\hat{\beta}\)` via [Gaussian elimination](https://en.wikipedia.org/wiki/LU_decomposition) `\(\Rightarrow\)` More numerically stable and being *much* faster. - R uses [QR decomposition](https://en.wikipedia.org/wiki/QR_decomposition). Its thin version can also well deals with colinearity (discussed later in this course). --- # Example - For example, here's a fake dataset of `\(n=5000\)` observations with `\(p=100\)` predictors. ``` r set.seed(2023-09-08) n <- 5000; p <- 100 X <- matrix(rnorm(n * p), n, p) y <- rnorm(n) ``` ``` r library(microbenchmark) microbenchmark(solve(t(X) %*% X) %*% t(X) %*% y, solve(crossprod(X), crossprod(X, y)), qr.coef(qr(X), y) ) #> Unit: milliseconds #> expr min lq mean median uq max neval #> solve(t(X) %*% X) %*% t(X) %*% y 63.67799 67.66804 73.22608 71.41587 75.14396 121.33167 100 #> solve(crossprod(X), crossprod(X, y)) 29.43764 30.49463 31.89378 31.11376 32.54883 58.43078 100 #> qr.coef(qr(X), y) 42.21364 44.81860 48.09981 47.81648 50.16340 90.78870 100 ``` --- # Colinearity ``` r W <- cbind(X, X[, 1] + rnorm(n, sd = 0.00000000000001)) solve(crossprod(W), crossprod(W, y)) #> Error in solve.default(crossprod(W), crossprod(W, y)): system is computationally singular: reciprocal condition number = 1.392e-16 ``` --- # QR decomposition ``` r qr.coef(qr(W), y) #> [1] 0.0207049604 -0.0107798798 -0.0053346446 -0.0139042768 -0.0165625816 -0.0247368954 -0.0055936520 -0.0050670925 #> [9] -0.0141895452 0.0014650371 0.0105871852 0.0236855005 -0.0009123881 0.0395699043 -0.0045459668 0.0156426008 #> [17] 0.0368986437 -0.0062241571 0.0003719454 -0.0001045447 0.0105437196 0.0032069072 -0.0099112962 0.0092091722 #> [25] -0.0056283760 -0.0101836666 0.0004409933 0.0079016686 0.0101626882 -0.0208409039 -0.0054924536 0.0064271925 #> [33] -0.0065590754 -0.0037863800 0.0072126283 -0.0013686652 -0.0261588414 -0.0045260288 -0.0204600332 -0.0108791075 #> [41] 0.0100509988 0.0021846634 0.0096076628 -0.0256744385 -0.0002072185 -0.0203092434 0.0199490920 0.0245456994 #> [49] 0.0141368132 -0.0075821183 -0.0331999816 0.0070728928 -0.0251681102 -0.0145501245 0.0124959304 0.0101724169 #> [57] -0.0041669575 0.0118368027 0.0058702645 0.0017322817 0.0008573064 -0.0068535688 -0.0101274630 -0.0093643459 #> [65] 0.0045194364 -0.0224489607 0.0175468581 0.0135508696 0.0048772551 0.0168445216 -0.0254587733 -0.0012700923 #> [73] -0.0106302388 -0.0017762102 0.0077490915 0.0110904920 -0.0144777066 -0.0079745076 0.0112005231 -0.0012697611 #> [81] -0.0024046193 -0.0094265032 0.0234028545 -0.0087827166 0.0097232715 -0.0188332734 -0.0151177605 0.0129435368 #> [89] -0.0086064316 0.0048073761 -0.0209634872 -0.0133873152 0.0203494525 0.0031885641 -0.0088269877 0.0064179865 #> [97] -0.0016902431 -0.0149829401 -0.0018118949 -0.0161594580 NA ``` --- # Eg4: Numerical optimization for MLE - The maximum likelihood estimate maximizes the log-likelihood `\(\ell(\theta)\)`. - For an interior solution, we often seek a root of the score equation: $$ \frac{\partial \ell(\theta)}{\partial \theta}=0. $$ - Closed-form solutions are uncommon. Newton-Raphson and BFGS find an approximate optimum iteratively. - Check the convergence code, gradient size, objective value, and sensitivity to starting values. 👉 Algorithms should agree when they reach the same optimum. Disagreement signals a computational problem or a different local optimum. --- # Eg5: Numerical integration Consider the integral $$ I=\int_0^1 \exp(-x^2)\,dx. $$ - It has no elementary antiderivative, but we can still approximate its value. - The composite trapezoidal rule replaces the curve by line segments over a grid. - Refining the grid from `\(m=100\)` to `\(m=1000\)` provides a simple accuracy check. 👉 Similar results under grid refinement support numerical stability, but do not prove exactness. --- # R Example: Grid refinement ```r trapezoid_exp <- function(m) { x <- seq(0, 1, length.out = m + 1) q <- exp(-x^2) h <- 1 / m h * (sum(q) - (q[1] + q[m + 1]) / 2) } I_100 <- trapezoid_exp(100) I_1000 <- trapezoid_exp(1000) c(grid_100 = I_100, grid_1000 = I_1000, difference = abs(I_1000 - I_100)) #> grid_100 grid_1000 difference #> 7.468180e-01 7.468241e-01 6.070031e-06 ``` --- # Monte Carlo alternative If `\(U\sim\operatorname{Unif}(0,1)\)`, then $$ I=E\{\exp(-U^2)\}. $$ ```r set.seed(123) M <- 1e4 u <- runif(M) g <- exp(-u^2) c(estimate = mean(g), trapezoid_reference = I_1000) #> estimate trapezoid_reference #> 0.7488739 0.7468241 ``` - Monte Carlo results vary across random samples. The MCSE measures simulation error. - For this smooth one-dimensional integral, the trapezoidal rule is usually more efficient. --- # The computational target determines the method First identify the mathematical target. Then choose an algorithm and a matching diagnostic. .small[ | Computational target | Common method | What to check | |:---|:---|:---| | Linear system or least squares | Matrix factorization | Residual, condition number, numerical rank | | Root of an equation | Numerical root finding | Equation residual, bracket or starting value | | Maximum or minimum | Numerical optimization | Convergence code, gradient, starting values | | Smooth low-dimensional integral | Numerical quadrature | Error estimate, tolerance, grid refinement | | Complex expectation | Monte Carlo | Number of draws, Monte Carlo standard error | ] The same target may allow several methods. Problem dimension, smoothness, and the required accuracy guide the choice. --- # Three sources of error .small[ | Source | What it means | Main control | |:---|:---|:---| | **Statistical error** | A finite data sample cannot reveal the population exactly | Collect more relevant information and report statistical uncertainty | | **Numerical and approximation error** | Rounding, ill-conditioning, early stopping, or a coarse grid changes the computed value | Use stable algorithms, tighter tolerances, and refinement checks | | **Simulation error** | A finite Monte Carlo or MCMC run changes across random samples | Increase effective draws and report the MCSE | ] More simulation cannot repair a poor model or remove uncertainty caused by limited observed data. --- # Core problems in computational statistics 1. **Numerical representation and stability** Floating-point arithmetic, overflow, cancellation, and ill-conditioned problems. 2. **Deterministic algorithms** Matrix factorization, root finding, optimization, numerical integration, and EM. 3. **Random simulation** Random number generation, Monte Carlo, resampling, and MCMC. 4. **Efficiency and scalability** Time, memory, problem dimension, and exploitable structure. 5. **Verification and reproducibility** Diagnostics, code, data, random seeds, and the computing environment. These themes define the objectives and structure of this course. --- # Unit objectives <div style="text-align: center; margin-top: 0.4em;"> <img src="parts-roadmap.png" style="width: 86%;" alt="Roadmap of the five parts of the textbook" /> </div> --- # Lab: Multivariate normal density Now, assume `\(X \sim N(\mu, \Sigma)\)`, can you do the following? 1. Write the `\(p\)`-dimensional multivariate normal density. 2. Discuss: how to evaluate it in computers? 3. Try to implement in R. *Hints:* 1. [Cholesky decomposition](https://en.wikipedia.org/wiki/Cholesky_decomposition): `\(\Sigma = R^TR\)`. 2. By this, you can also easily calculate the determinant of `\(\Sigma\)`. 3. This example demonstrates how statistical computing bridges theory and computation: theory defines `\(f(x)\)`, but computation makes `\(f(x)\)` actually evaluable. --- # About assignments 1. Please use **SPOC** for assignment submission. 2. Only one single pdf or html file is acceptable. I recommend you write your assignments using [Rmarkdown](https://rmarkdown.rstudio.com/), a productive notebook interface to weave together narrative text and code to produce elegantly formatted output. 3. Use meaningful file names: `Name_StudentNO_n.pdf`. --- # References Chapter 1 of our textbook.